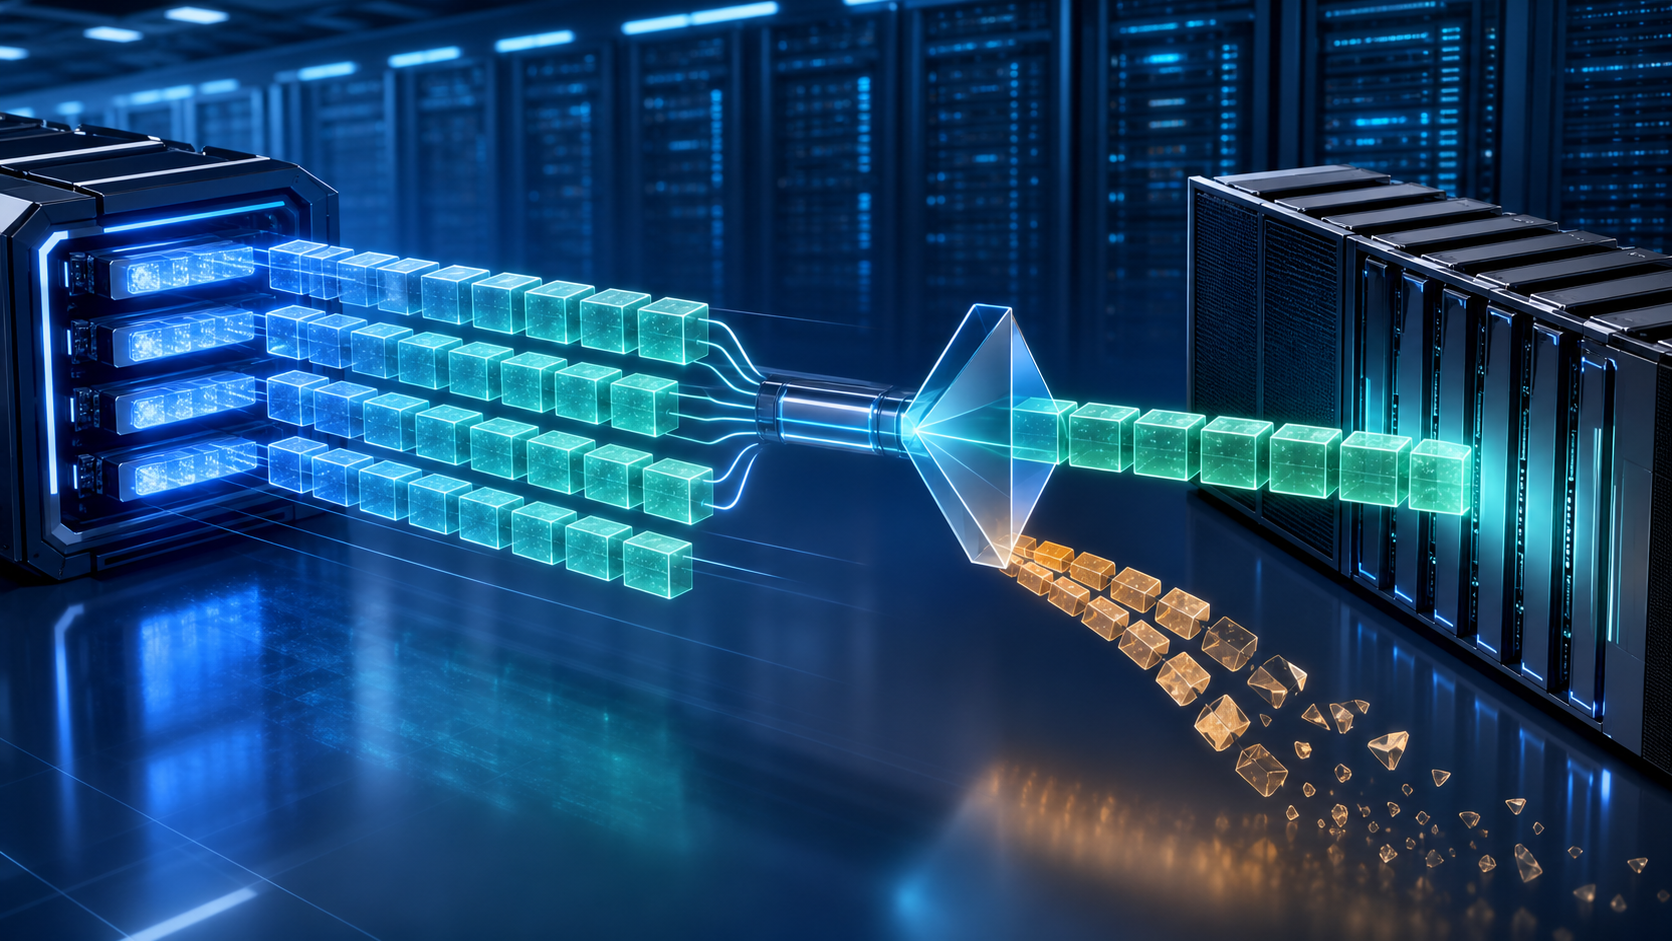
Abstract illustration of DSpark routing confident drafted tokens through a verification scheduler

DSpark Explained: DeepSeek's Confidence-Scheduled Speculative Decoding

DeepSeek recently open-sourced DeepSpec, a codebase for training and evaluating speculative decoding draft models, along with the DSpark paper and checkpoints. I wanted to understand what is actually new here, because speculative decoding itself is not new. The older idea is already powerful: use a small draft model to propose tokens, then let the large target model verify them. I explained that foundation in Speculative Decoding Explained. DSpark is interesting because it attacks two practical problems that show up when speculative decoding moves from a paper idea into production serving: ...

June 29, 2026 · 11 min · Nitin
How Attention EvolvedFrom sequence-to-sequence alignment to long-context decoder efficiency.2014Bahdanauadditive attention2015Luongdot-product styles2017Transformermulti-head self-attn2019-2023Sparse, local,linear, MQA, GQA2024-2025DeepSeekMLA focusThe trend is consistent: keep the expressive power of attention, then remove its biggest bottlenecks.

Attention Mechanisms Explained: Self-Attention, Cross-Attention, Sparse Attention, MQA, GQA, and DeepSeek MLA

Attention is the idea that made modern transformers practical and powerful. Instead of compressing an entire input into one fixed vector, a model can decide, token by token, which earlier pieces of information matter most right now. That sounds simple, but there are many different kinds of attention mechanisms, and they exist because models face different constraints: some need strong alignment between an encoder and a decoder some need to generate text one token at a time without looking ahead some need to handle very long documents some need to reduce GPU memory traffic at inference time This article walks through the main families of attention, shows where they fit, and explains why newer variants such as DeepSeek’s multi-head latent attention (MLA) matter. ...

March 9, 2026 · 14 min · Nitin